
IoT Alert Fatigue: 7 Proven Fixes for Factory Teams in 2026
Picture a night-shift supervisor whose phone buzzes forty times before midnight.
Thirty-nine of those alerts say nothing useful. A sensor flickered, a gateway reconnected, a temperature crossed a line and came back. By the fortieth, he stops looking.
That is IoT alert fatigue, and it is one of the quietest risks on a connected shop floor. The supervisor in this story is made up, but the pattern is real. The alert that matters arrives looking exactly like the ones that do not.
At IoT Mail Bridge, we send and route machine alerts for a living, so we see this daily. This guide explains the problem, shows a benchmark you can check against, and gives seven fixes you can start this month.
What is IoT alert fatigue, and why does it hit factories?
IoT alert fatigue is what happens when sensors and software send more notifications than people can act on, so they start ignoring them. Factories feel it hardest because machines raise alerts all day, and most of those do not need a human. The real fault then hides in the noise.
It builds up slowly. A new sensor goes live, a threshold is set cautiously, and an alert is copied for a second team. Six months later nobody remembers why half the messages exist.
The stakes are not small. The UK Health and Safety Executive’s case summary on the 1994 Texaco refinery explosion at Milford Haven lists this finding: “Excessive number of alarms in emergency situation reduced effectiveness of operator response.” Process Engineering magazine adds that 87% of the alarms at that refinery were set to high priority.
Your plant is not a refinery, and a missed alert on a packaging line is not the same event. But the lesson carries over. When every message shouts, people hear none of them.
If your sensor data is shaky to begin with, fix that first. Our checklist for deploying industrial IoT sensors covers the groundwork.
How many alerts can one operator handle before IoT alert fatigue sets in?
Guidance based on EEMUA-191, ISA-18.2 and IEC 62682 targets under 288 alarms per operator per day, or one to two every 10 minutes. Above 432 a day, or more than three per 10 minutes, calls for action, per Emerson. These are control-room benchmarks, so use them as a starting point.
These numbers come from Emerson’s alarm management by numbers paper, which bases them on the three standards above. They were written for process control rooms, not every IoT setup. Still, they give you something to measure against, and that beats guessing.
| Metric | Target | Action limit |
|---|---|---|
| Alarms per operator per day | Fewer than 288 | More than 432 |
| Alarms per operator per 10 minutes | 1 to 2 | More than 3 |
| Share of time in alarm flood | Below 1% | Above 5% |
A flood is a burst. Under EEMUA-191, it starts in a 10-minute window with more than 10 new alarms and ends when a window has fewer than five. A simpler rule treats any 10-minute window with more than 10 new alarms as a flood.
IoT Mail Bridge suggests a simple start: count your own alerts for one week before you start fighting IoT alert fatigue. Most teams are surprised by the answer.
What are the 7 proven fixes for IoT alert fatigue?
Remove alerts that need no action, tune thresholds and delays, group alerts with one cause, set real priorities, route each alert to its owner, send low-priority items as digests, and review monthly. Do them in that order, because each step makes the next one easier.
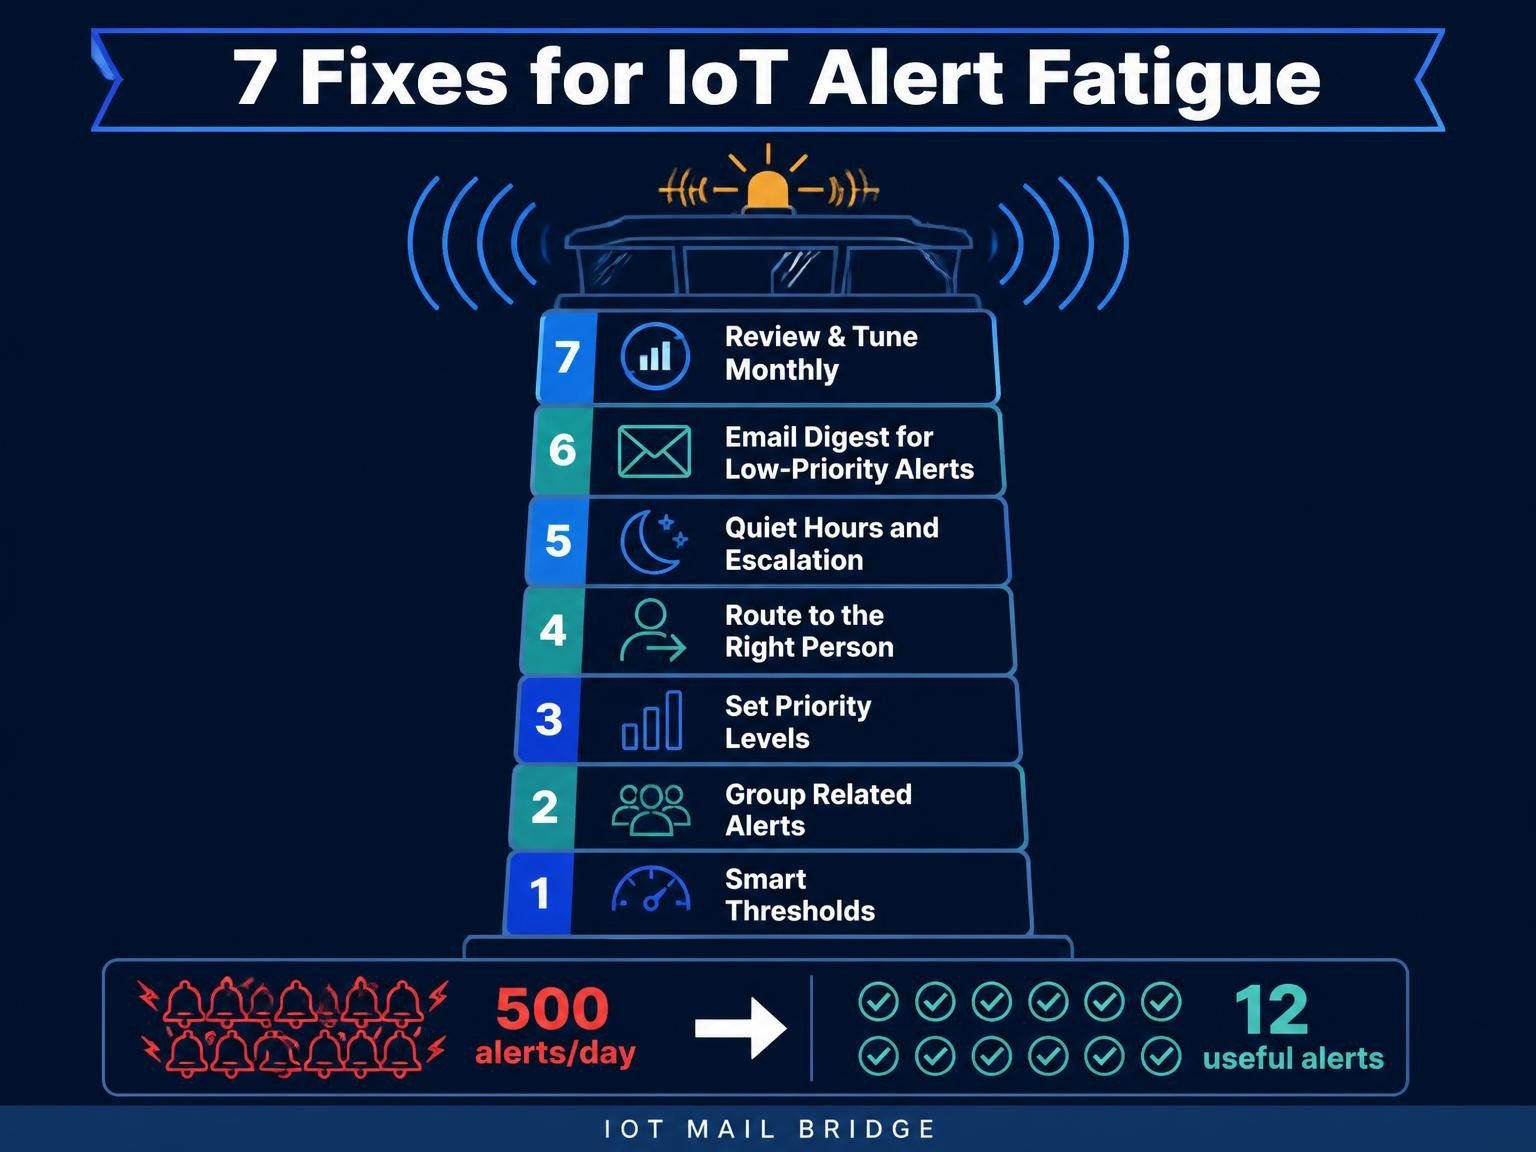
Fix 1: Remove alerts that need no action
Ask one question of every alert: what will a person do when it fires? If the answer is nothing, delete it or move it to a quiet log. This single pass usually cuts more IoT alert fatigue than any new tool.
Fix 2: Use smart thresholds and delays
Fixed limits ignore normal swings. Set thresholds around real operating ranges and add a short delay, so a two-second spike does not wake anyone. Keep the delay small. A delay that is too long hides a real fault.
Fix 3: Group alerts that share one cause
One failed gateway can trigger forty alerts from forty sensors behind it. Link them so the root cause sends one alert and the rest stay quiet. This is where predictive models help, as covered in our guide on how predictive maintenance uses machine learning to catch equipment failures early. For the wider plant view, see this smart factory productivity guide.
Fix 4: Set real priority levels
Keep the top tier rare. A useful rule is that urgent means someone must act now. Everything else is a lower tier. The Pembroke figure above, 87% set to high, shows what happens when that rule is skipped.
Fix 5: Route alerts to the owner
At IoT Mail Bridge, we start every client setup by naming an owner. Send each alert to the person who can fix it, and decide in advance who is next if nobody responds. A message to a shared inbox is a message nobody owns. More on this in the next section.
Fix 6: Send low-priority alerts as a digest
Routine items such as battery low, firmware notices or daily totals can wait. Bundle them into one scheduled email. People read a single digest far more reliably than thirty separate pings, which eases IoT alert fatigue.
Fix 7: Review and retune every month
Alert settings age fast, and IoT alert fatigue creeps back if nobody reviews them. Once a month, list the ten noisiest sensors, ask why, and fix the cause. Pair this with predictive maintenance on IoT Insights Hub for ideas on spotting trouble early.
| Fix | Effort | Where it helps most |
|---|---|---|
| 1. Remove no-action alerts | Low | Fast cut in volume |
| 2. Smart thresholds and delays | Medium | Fewer false alarms |
| 3. Group by root cause | Medium | Alert floods |
| 4. Real priority levels | Low | Faster response to urgent faults |
| 5. Route to the owner | Medium | Unread or ignored alerts |
| 6. Digest for low priority | Low | Inbox and phone noise |
| 7. Monthly review | Low, ongoing | Keeping gains in place |
Effort levels are our own judgement from client setups, not a measured study. Your mix will differ.
How do you route alerts so the right person reads them?
Match each alert to one owner, one channel and one escalation step. Urgent faults go to a phone call or SMS. Routine items go to a digest email. Add throttling so a repeating sensor cannot send the same message fifty times, and track delivery so you know it landed.
Detection is only half the job. An alert that never reaches a human has done nothing, and that is how IoT alert fatigue turns into missed faults. This is the layer IoT Mail Bridge works on, and it is where many setups break.
Email still does a lot of honest work here. It reaches supervisors away from the control room, and it leaves a log. Read our notes on a reliable SMTP relay for IoT and M2M fleet alerts and how to set up IoT email automation the right way for the technical side.
- Throttle repeats. One sensor should not send the same alert more than once in a set window.
- Escalate if unread. If the first person does not acknowledge in time, move to the next.
- Use the right channel. Phone or SMS for urgent, email for the rest.
- Track delivery. Know which messages bounced, were delayed or never opened.
The same pattern shows up in sales teams. ARS B2B Social Bridge has written about sales ignoring marketing leads, and the cause is familiar: too many leads, no clear owner, no follow-up path. Factories and sales desks fail in similar ways.
Transport matters too. what MQTT is and how it moves sensor data if you want to see how readings travel before they become alerts, and our piece on edge to cloud data security for IoT fleets covers keeping that path safe.
How do you measure whether IoT alert fatigue is getting better?
Track four numbers: alerts per operator per day, alerts per 10 minutes, the share of alerts that led to action, and time to acknowledge. If volume drops while response to real faults gets faster, IoT alert fatigue is improving. Review them monthly and retune.
- Take a baseline. Count alerts for one normal week before any change to your IoT alert fatigue plan.
- Tag outcomes. Mark each alert as acted on, ignored or false.
- Change one thing at a time. Otherwise you cannot tell what worked.
- Compare weekly. Look at the benchmark table above.
- Watch for misses. Check that no real fault slipped through after a cut.
Good measurement needs a sound data design underneath, and IoT Mail Bridge sees teams skip it often. See the industrial IoT architecture guide from IoT Insights Hub for how the pieces fit, and cutting factory downtime with industrial IoT for the cost side.
What do critics say about cutting factory alerts?
Critics say cutting alerts to fight IoT alert fatigue can hide slow-building faults, that control-room benchmarks do not fit every IoT setup, and that AI filters can become a black box. Supporters say fewer, better alerts get faster responses. Both are right, which is why every change needs a review.
What the careful voices say
- Fewer alerts can mean missed faults. A threshold set too wide can let a slow problem grow. Keep a quiet log and review it.
- Benchmarks are not universal. The 288-a-day target comes from process control rooms. A small plant with one operator may need stricter numbers.
- AI filtering needs scrutiny. A tool that hides alerts for you must show its reasoning. Before you buy one, read The Business Perspective on AI wrapper versus deep tech startup and ask what sits under the hood.
What supporters say
- Quiet systems get trusted. When alerts are rare, people react. That is the point of the HSE recommendation that alarms be limited to what an operator can effectively monitor.
- Software can help. As industrial AI agents spread, so will automated alerts. Funding keeps flowing, as shown in AI agent startup funding in September 2026, so the volume problem will grow before it shrinks.
Our view at IoT Mail Bridge, after years of routing machine alerts: remove noise, but never remove visibility. A quiet log and a monthly review are your safety net.
What are the most common questions about IoT alert fatigue?
People mostly ask what the problem is, how many alerts are too many, what causes it and whether email still works. IoT Mail Bridge answers six common questions below, each with a clear limit or a named source.
What is IoT alert fatigue?
IoT alert fatigue happens when connected sensors and software send so many notifications that people stop reacting to them. Operators start muting, skipping or auto-clearing messages. Real faults then get lost among false alarms. It is a people problem caused by badly tuned alerts, not by lazy staff.
How many alerts is too many for one operator?
Process-industry guidance based on EEMUA-191, ISA-18.2 and IEC 62682 targets under 288 alarms per operator per day, or 1 to 2 per 10 minutes. Above 432 a day, or more than 3 per 10 minutes, calls for action, per Emerson. These are control-room benchmarks, so adapt them.
What causes IoT alert fatigue in factories?
Mostly fixed thresholds that ignore normal swings, duplicate alerts for one root cause, and every alert marked high priority. Add unclear ownership and alerts that need no action, and the noise grows quickly. Fixing the alert design usually removes more noise than adding staff or screens.
Should I just turn off low-priority IoT alerts?
Not blindly. Switching alerts off without review can hide a slow-building fault. Instead, ask what action each alert triggers. If the answer is none, remove it. If action can wait, move it to a daily email digest. Keep a record of what you changed and why.
Is email still a good way to send factory alerts?
Yes, for non-urgent alerts, digests and anything needing an audit trail. Email reaches supervisors who are away from the control room and is easy to log. Use it with throttling and delivery tracking, and keep SMS or phone calls for urgent faults. One channel rarely fits every alert.
How do I know if my alert fatigue fix is working?
Track alerts per operator per day, alerts per 10 minutes, the share of alerts that led to action, and time to acknowledge. If total volume falls while response time to real faults improves, the fix is working. Review the numbers every month and retune thresholds.
What is the bottom line on IoT alert fatigue?
IoT alert fatigue is fixable. Count your alerts, remove the ones that need no action, group the rest, route them to owners and review monthly. Start with one line or one team. IoT Mail Bridge can help you build the delivery path.
Go back to the supervisor and his phone. The goal is not zero alerts. It is that when the forty-first buzz comes, he knows it matters.
Take the benchmark table to your next shift meeting, count one week of alerts and pick the first fix. If IoT alert fatigue is eating your team’s attention, the quickest win is simply deleting the messages nobody acts on. For more on sensors and automation, browse IoT Insights Hub.
One thought on “IoT Alert Fatigue: 7 Proven Fixes for Factory Teams in 2026”